
Aden Mann
Applied AI, independent
Australia
Aden Mann: Operator-grade
AI.
I build applied AI systems for work where being wrong is expensive. I work independently now; before that, four years at Immutable, a US$2.5B web3 company, building its AI and automation capability out of finance operations. Eleven years flying Army helicopters and an MBA came first.
The main theme for me is operations at the hard end: systems that break at bad moments, decisions with real stakes, and the gap between what a tool is supposed to do and what it actually does under pressure. Army aviation went digital partway through my career. Watching that transition up close, including unpacking where it went wrong as an aviation safety investigator, is where I developed a view on how human-machine work actually transfers, and how it fails.
01 Builds
AutoEvaluation
An optimisation loop that hill-climbs LLM instructions against a scoring function. Each round makes one change, keeps it if the score goes up and reverts it if it doesn't. Unlike DSPy, TextGrad and MIPRO, it doesn't need a Python pipeline.
github.com/AdenCJM/AutoEvaluation ↗ (opens in a new tab)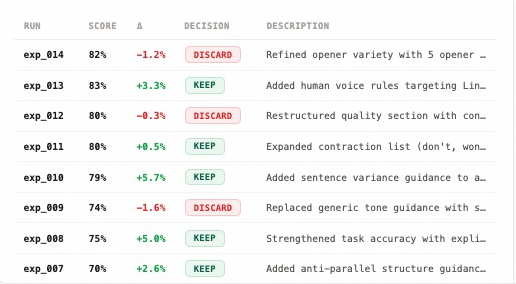
Parallel Research
Sends one research question to Claude, GPT, Gemini and Perplexity at the same time, then compares the answers to show where they agree and where one model is out on its own.
github.com/AdenCJM/parallel-research ↗ (opens in a new tab)AI Fluency Framework
A five-level, six-function matrix for measuring AI capability across a company. I built it while rolling out AI at a scale-up, after seat count stopped being a useful metric: a licence shows who's paying for the tool and nothing about who can use it.
Read the framework →02 Live agent
Ask AI Aden
An agent that answers the way I would, running live on this page.
“How do you know a prompt change actually made things better?”
03 Writing
- Speaker on applied AI and AI strategy, New York, Sydney and Melbourne
If you're working on something in this space, I'd like to hear how you're approaching it. I'm open to advisory and fractional work, and the right full-time role.
aden@adenmann.com →